Suggested Reading
•
September 28, 2026
View


Artist and engineer Ryan Murdock authored BigSleep, the foundational open-source notebook that paired BigGAN with OpenAI's CLIP. Less than a day after CLIP's release in January 2021, he posted a white clock that opened text-to-image generation to anyone with a browser. Murdock spoke with Peter Bauman (Monk Antony) about the lasting significance of one of the first widely available, open-source text-to-image techniques. They discuss the hacker ethos and story behind BigSleep's origins, Murdock’s own roots in Processing, glitch art and CPPN GANs, plus what the latent space reveals about ourselves.
Peter Bauman: I heard you say that you got into machine learning (ML) at 16. How did you hear about it and get started at that age?
Ryan Murdock: When I was 16 I was mostly doing procedural art. So it would have been Processing. I did a lot of visualizers back then with projectM.
A lot of what I was initially working on was old-school generative art, using stochastic input and RNG but with your hand-coded dynamics. You try to make something interesting and most of the time it will incorporate some randomness.
I was probably closer to 18 when I started doing ML generative art. In that transition, I remember watching a Coding Train tutorial by Daniel Shiffman doing a perceptron and thinking, “This is so neat.”
I was really interested in this idea that you could do learning with these relatively simple rules. They make it so the system eventually settles into this place where it has learned to do a task.
The first project that I did was adapting the perceptron and implementing backprop through a multilayer perceptron. I don't know if I ended up doing a convolutional net back then. I hooked up a webcam to the pretty small perceptron and visualized it.
Definitely in hindsight using Processing for backprop is a funny idea because it's kind of the wrong place to put it. I'm sure that TensorFlow and Keras and all of these other libraries already existed.
Peter Bauman: That whole MIT-Processing scene was also entrenched in ML with Casey Reas, Tom White and Golan Levin. So you got into ML at 18 and what year was that?
Ryan Murdock: The tutorial stuff with Shiffman was in 2018. I would have been about twenty at the point when I was doing CPPN (compositional pattern-producing networks) and GANs. So I'd been doing it for a little while at that point. I was really interested in glitch art for a very long time.
In some ways, generative and glitch art are adjacent to hacker culture, saying “We'll break things to try and make something pretty.” That definitely inspired the approach to working with CLIP.
The CPPNs were a predecessor to SIRENs. Basically, you give a point along a grid to the neural network and it produces a pixel color at that point. You're almost doing a shader where the computations are of neural networks. That was another one of the earlier things I worked on.
Maybe the first novel, or at least novel-ish, thing that I did was taking the CPPN and using it for a GAN. I think that people had been using CPPNs for a lot of interesting work, but I don't know if it had been as often applied to adversarial learning.
I did a lot of studies with that where I was training it on tree datasets and that sort of thing.
Peter Bauman: How did working with CPPNs lead to you thinking about text-to-image with GANs?
Ryan Murdock: Back in those days, doing text-to-image with a GAN wasn’t really possible. There were papers where they were doing this sort of thing but it was always on really limited datasets. It would be birds and their names or flowers with the name of the flower. So if you tried to even do something like a stop sign, a lot of the time it wasn't really recognizable.
Back then it was just for love of the game that people would train these sorts of GANs.
For CPPNs in particular, when I was training them, you get these images that are, in Aaron Hertzmann’s phrase, visually indeterminate and have a pretty identifiable style. At that time, you would have a theme. A lot of people would do nudes or flowers or those sorts of things. But in my case a lot of the time I'd be like:
“I want to see what I can make by just hacking away at it.” I thought it was an interesting way to make an interesting image.
A lot of the time my subjects were just trees. I would collect my own little datasets of trees and try and get a pretty-looking tree image.
I totally think that hacker ethos of, “We're going to crack it open and we're going to share it and it's going to be really interesting,” was definitely at least in the back of my mind.
In some ways that's a really justifiable way of thinking about web-scale ML, because it's the fruit of everybody's labor.
Essentially anyone who's posted online has roundabout contributed. So why not make the artifact itself open?
Peter Bauman: You had that inclination to combine things already. Then it was the very beginning of 2021 in early January when OpenAI released CLIP. That was about a year after those GAN and CPPN experiments? How did it get to a point where as soon as CLIP came out you knew right away what to do with it?
Ryan Murdock: It's funny because in hindsight, I had been working on feature visualization for these classification networks. The convolutional neural network flavors of CLIP would look very similar to some of these classifier networks that I was doing feature visualization on.
DeepDream (2015) was this really cool work using feature visualization to make these super psychedelic images. I was using very similar techniques to make these relatively more boring images.
It was like, “Let’s get the most archetypal orange out of the VGG classifier labels as possible, while reducing the sort of noise and adversarial artifacts as much as possible.”
Doing that work when CLIP was released, it was like, “Now there's this thing where instead of having 1,000 classes, it has a score for the fit for literally any text.”
I was looking at it and it actually did take some thought. I remember my brain kind of being like, “Wait, is this actually… Can't you just use this to make any text?”
You're really doing the same sort of thing where instead of trying to maximize the probability that it's an orange, you're trying to maximize the rating that you can get.
Peter Bauman: It's interesting the central role of Alec Radford who not only was the lead author of CLIP but also created DCGANs and led the original two GPT papers. What was special about CLIP though?
Ryan Murdock: Yeah, it's pretty amazing. I feel like CLIP was especially compelling. When it came out everyone was freaking out. That’s because it went from this paradigm of “We have access to a thousand classes that we can work with but that maybe our data is too constrained to have super clear imagery for.”
Then, particularly with CLIP, it cracked open the thinking that “We don't even have to hand-engineer what we're interested in from this model.”
When you decide what you're interested in, it makes it so that the tuning of the model and the use of its super generalist weights means you can be even better at tasks around the small set of things that you are interested in.
But taking the already interesting world of, “You can classify this large set of things,” and taking it to, “You can get a score for literally any idea you can think of.” That in and of itself is super, super exciting.
Peter Bauman: How did it actually work on the day CLIP came out? You posted the famous white clock image less than twenty-four hours after CLIP’s release. Was that BigSleep right away or a different system at first?
Ryan Murdock: The tweet was pretty quick but it took me a while to actually release something. It really was something that slotted into a situation where I had everything already set up to do something with “Let's make the most orange orange that we can.”
So it probably was not many hours of work to get the first notebook that I was using, which actually was a SIREN model with CLIP called Deep Daze. There's this interesting thing where if you're training a SIREN model or a CPPN, you can give fractional points for the coordinate so you can basically have whatever resolution image you want.
I talk a lot less about the Deep Daze notebook even though it came out before BigSleep in mid-January 2021. It could do really whatever resolution you wanted, which I found interesting in and of itself: this idea of you can morph even within the image in these interesting ways.
Deep Daze was just a less texturally interesting version of BigSleep. The thing that I love about BigSleep is the textures. But with Deep Daze, it didn't really have a prior. It was just totally randomly initialized.
It produced outputs that looked more like DALL·E, which was quite a bit more smooth. But Deep Daze had lower text alignment than the DALL·E 1 outputs that they showed.
Peter Bauman: Did you get any sleep that first night?
Ryan Murdock: I mean, I definitely was excited. I remember the first one where I realized it was working; it was a white clock. It was interesting because I didn't just write “clock” and it showed the clock. It also had all of these random people in the image.
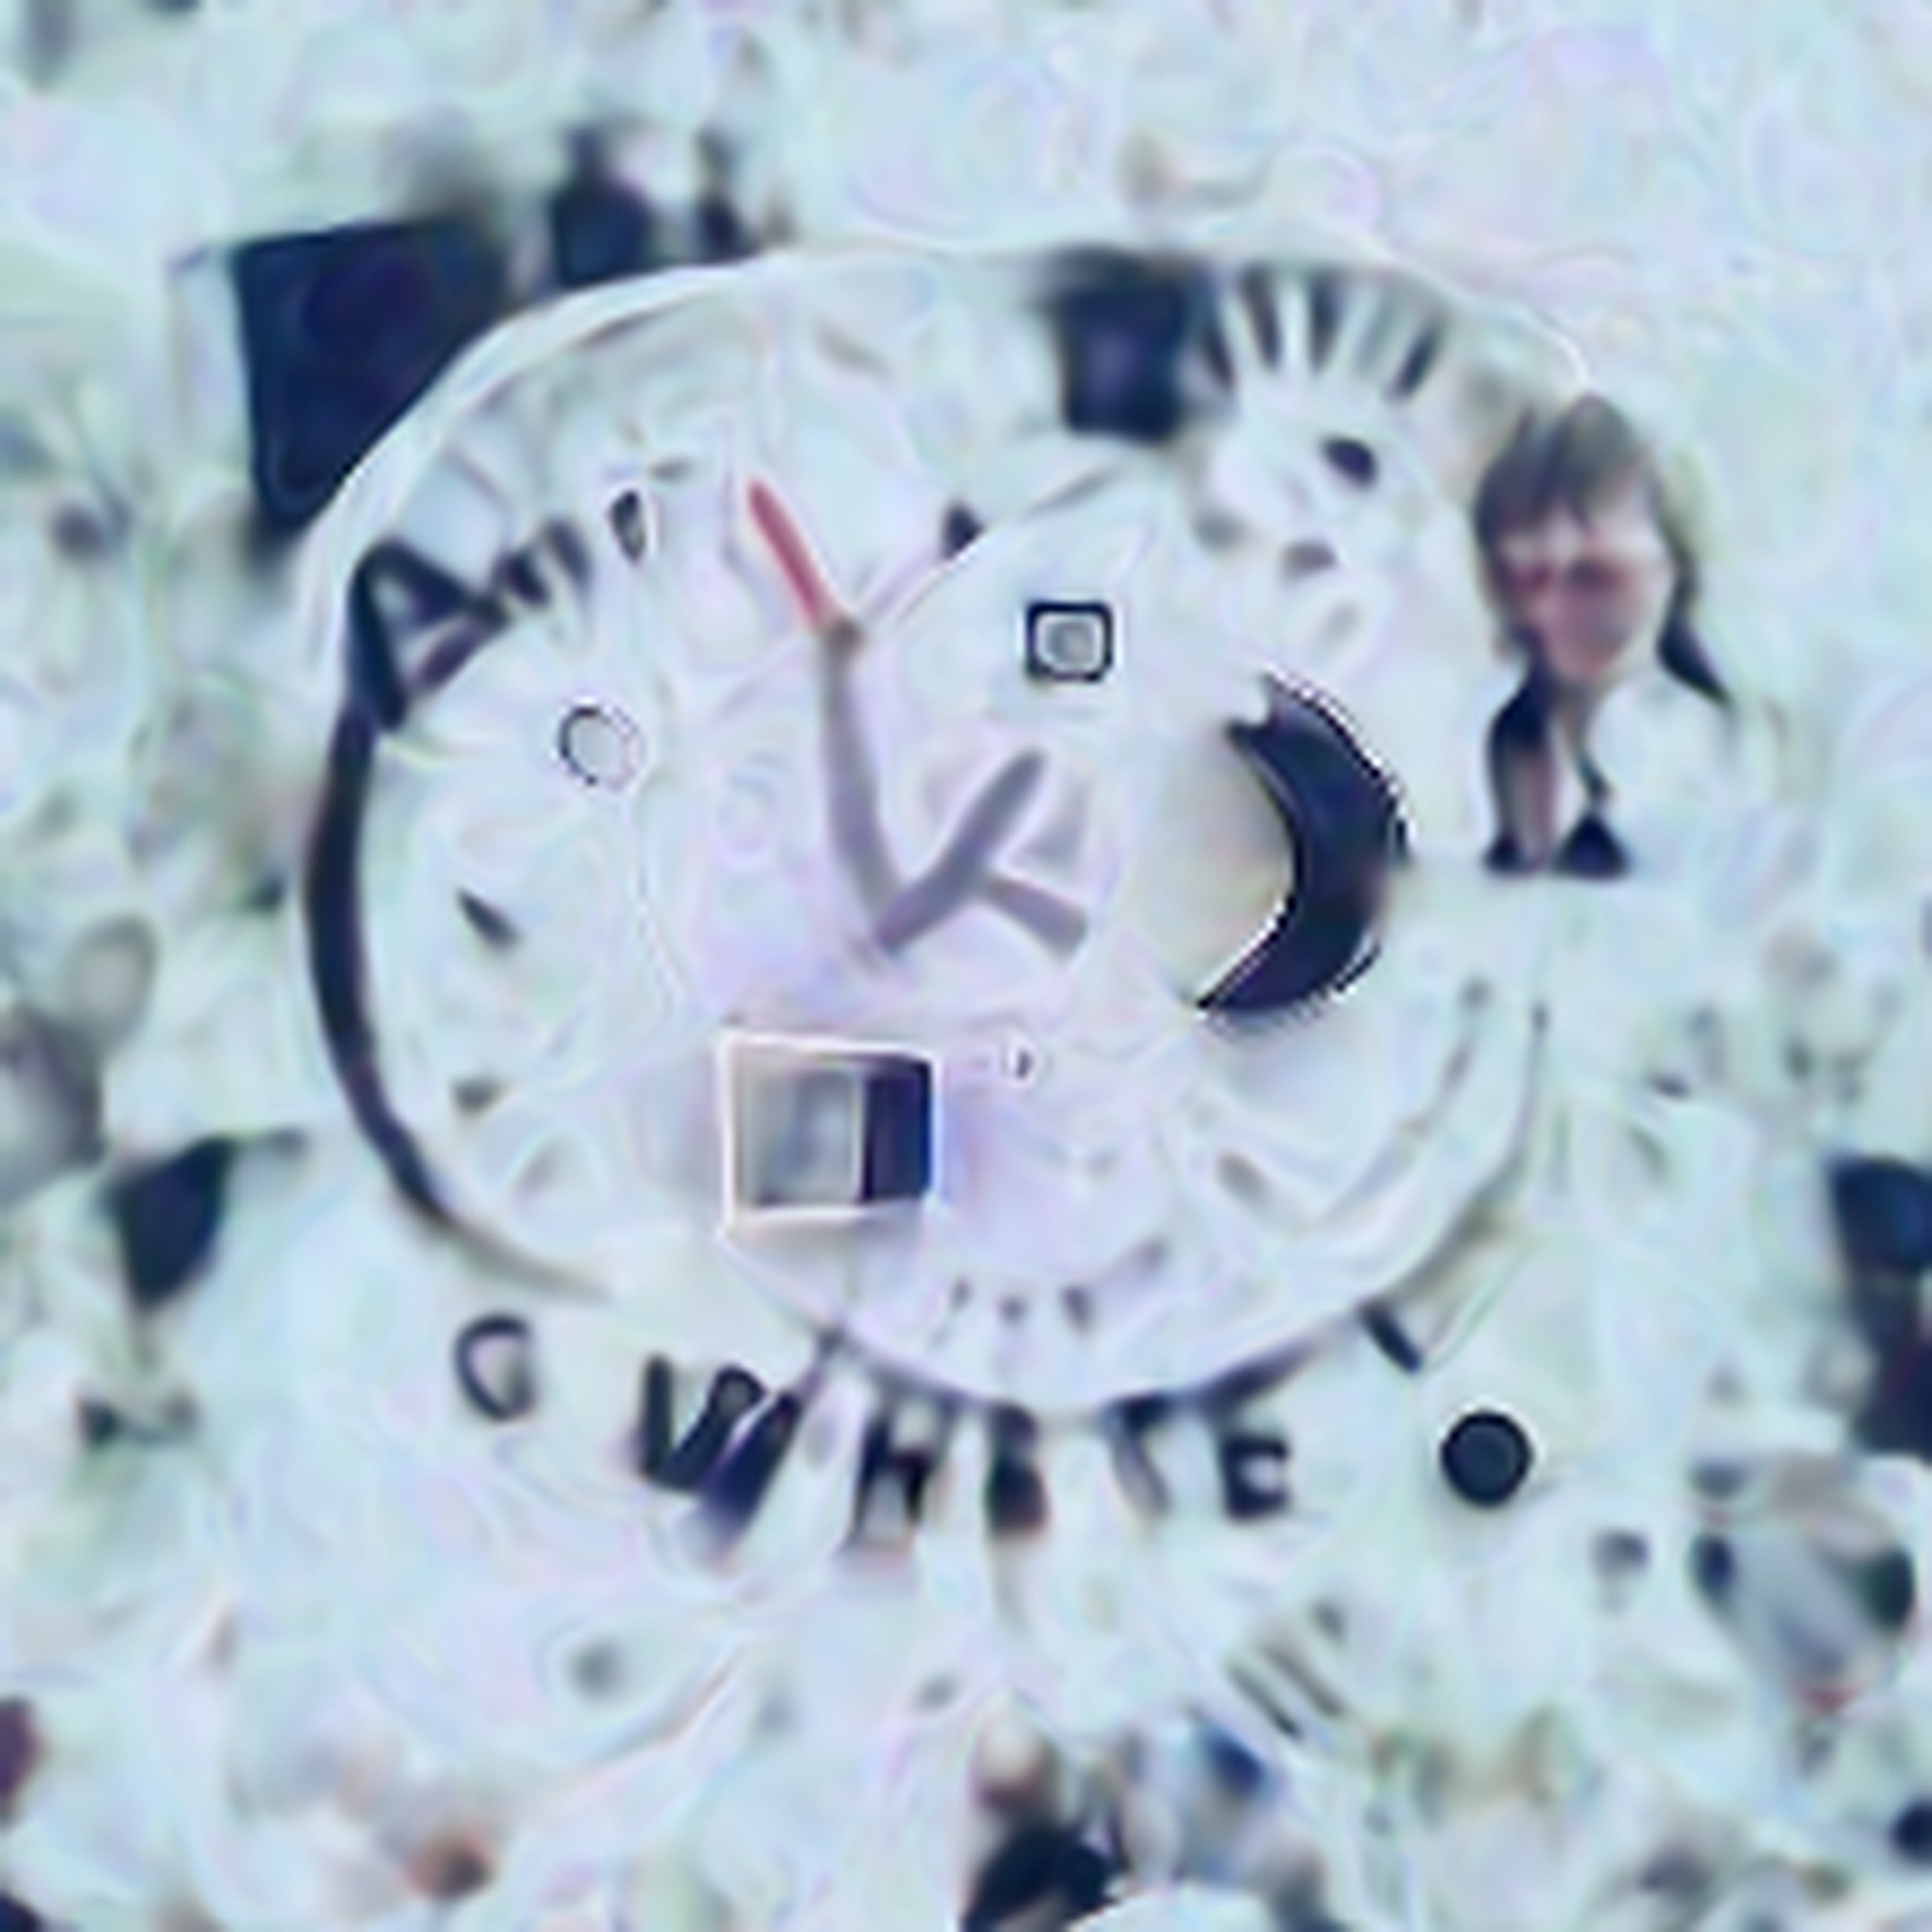
That was definitely when I thought: you could not, with generative art back then, give an input and see the visual text being written out and all these weird kind of random characters kind of being involved. That was definitely very exciting.
Peter Bauman: So what was the process of getting from Deep Daze to BigSleep and something you could share publicly?
Ryan Murdock: Back in those days, a lot of the work was trying to figure out how to avoid adversarial artifacts. That’s where you have this misalignment between what a person sees and associates with the class label or with the text input.
One way to deal with that is augmentation. In particular, there’s a type of augmentation where you take the image and say, “I'm going to crop it at all these different places and then I'm going to resize it. And I'm going to take the gradient through all of these different crops and resizings of the image.”
So a lot of the work back then felt almost sculptural, where you were tuning the hyperparameters and trying to get just the right mixture. You could get different qualities from the output depending on how you tuned it. Maybe the texture would be really striking in one way and maybe the overall consistency and fidelity would be really striking the other way.
A lot of the work then was deciding what augmentations to apply. Can it speed up the process? Can it improve some aspects of it? It was to taste, where different qualities were maybe only interesting to a visual artist in a lot of ways.

Peter Bauman: This story is also interesting because Katherine Crowson was doing something very similar but entirely in parallel. Did you two ever meet or discuss what you were both working on independently?
Ryan Murdock: In the VQGAN days in particular we were doing super similar work. I've talked to her in Twitter DMs and I think a few times over Discord.
She's super cool in the times we have talked. Even aside from the VQGAN, her research work is super, super cool.
But we haven't gotten the chance to chat ever in person or anything like that, which is too bad.
Peter Bauman: As with VQGAN, I'm curious how many of the BigSleep outputs ended up minted on Tezos. How did you hear about it? And are you happy you did that in retrospect?
Ryan Murdock: In terms of just knowing about the world of crypto, when I was younger around when I was doing Processing stuff at 16, I actually was using Bitcoin for online gambling. Not that much but it was definitely illegal, especially for a minor to be gambling online in Utah with crypto.
I remember I had that experience of buying something—it was like 500 bucks—but it was a bit like the buying-a-pizza-with-your-Bitcoin experience. I had definitely been following this sort of thing for a while.
For Tezos in particular, part of it was being quite interested in the differences between proof of work and proof of stake. The idea of enforcing the “reality” of the chain using either brute-force compute or the stake that people have in it is really interesting: that raw material versus social dichotomy.
The other reason I chose it was because I knew that Mario Klingemann, Helena Sarin and many other people I'd been following for years and years and years were working there and putting their art there.
That was the big reason that I chose to put things there. And I really enjoyed it and that scene quite a bit. It exposed me to some artists that I'd never seen before.
Peter Bauman: Do you see the blockchain as having played a valuable role in the preservation and visibility of the work?
Ryan Murdock: Services like InterPlanetary File System (IPFS) help. It goes back to how it feels like things rot away and everything has to be archived. I always talked about it as signed digital prints and really honestly thought about it.
There is a value to the mindset of, “I am seriously publishing this and I am going to make sure that it survives in part because I'm publishing it.”
Peter Bauman: Maybe the most fascinating part about those first public text-to-image models was how they let artists easily explore the latent space for perhaps the first time, especially with something approaching natural language. It’s almost like discovering a different realm of reality.
Ryan Murdock: Thinking about the art in terms of a latent space, it's interesting because in some ways with SIREN I was probably not even using a latent vector and a latent space per se. With BigGAN it's like you are using a latent space in the proper sense.
The latent space is in some ways a conceptual thing. What's funny is that the way people talk about it in philosophy versus math and machine learning can diverge.
You can have a proper latent variable model with a VAE where you're saying this specific vector, string of numbers, is representing some latent variable. Then you can have a latent variable where you're literally saying, “We want to see if this thing that we believe exists in the real world, like depression and anxiety, is an actual thing that exists but that we can't directly measure.”
In some ways there's exploring this latent space of BigGAN that already existed. The continuity there really was fun. Because we already have these really aesthetically interesting images that are visually indeterminate.
Then being able to use text to explore that area was really, really exciting.
It was the same sort of exciting idea that we don't have to be constrained to a set of classes when we cover all of these many, many concepts. It’s that same idea with the generative aspect where it's like, “I can go find an infinite set of things that might be interesting.” That was really exciting.
Peter Bauman: The latent space as this distillation of humanity is terribly exciting and scary. Can you talk about what latent space exploration reveals about us and our knowledge, our history?
Ryan Murdock: I was really, really interested in homing into the sociological aspects of it. We have tried our best to distill the information of the whole internet into this thing, and in doing so kind of by proxy everything that people know or can know.
In a lot of cases I'd be looking out for what kind of biases we could find within the network. Generating an image of a CEO, for example, was problematic in terms of representation, especially back then. The results were very likely to be super bad.
Even aside from the social aspect, there are really interesting things you can investigate with this representation that's trying to fit the internet as well as possible.
You can search for the archetypal example of an idea or of a thing. It’s interesting because if you generate a certain string of words you'll sometimes get these recurring Loab-esque representations of it, which I do think would probably generalize even if you use newer models like SigLIP, where it's encoded in the data itself.
With ideas like Phillip Isola and colleagues’ Platonic representation hypothesis, there's always this question—and I think there are ways of getting at the question—of how much of the representation is truly, philosophically, almost pure, and how much of it is just the way that the data works:
what we have in the dataset itself, which we've managed to fit but still has some potentially incidental things going on in it.
Peter Bauman: A lot of latent space exploration can be reduced to slop. How do you see the connection between hand-coded, non-ML generative art and art incorporating deep learning generative AI models?
Ryan Murdock: I think it's understandable that people see a lot of really low-effort spam coming out of these models and feel like it's always been the majority of the output. When something gets a hold online, there's always going to be the lowest common denominator output of literal spam and low effort things.
In terms of the art, the least charitable framing of the connection between procedural generative art and model-based ML generative art, is it's a fall from grace. But they're still so connected. It's still a lot of the same people, like you mentioned, who are going into this. Or they grew up in procedural and then moved into ML or brought some of that ML work forward. I totally think it's so, so, so connected.
------
Ryan Murdock is an artist and machine learning researcher focused on multimodal generative systems. He authored the popular open-source BigSleep notebook and co-pioneered the approach of combining VQGAN and CLIP.
Peter Bauman (Monk Antony) is Le Random's editor in chief.